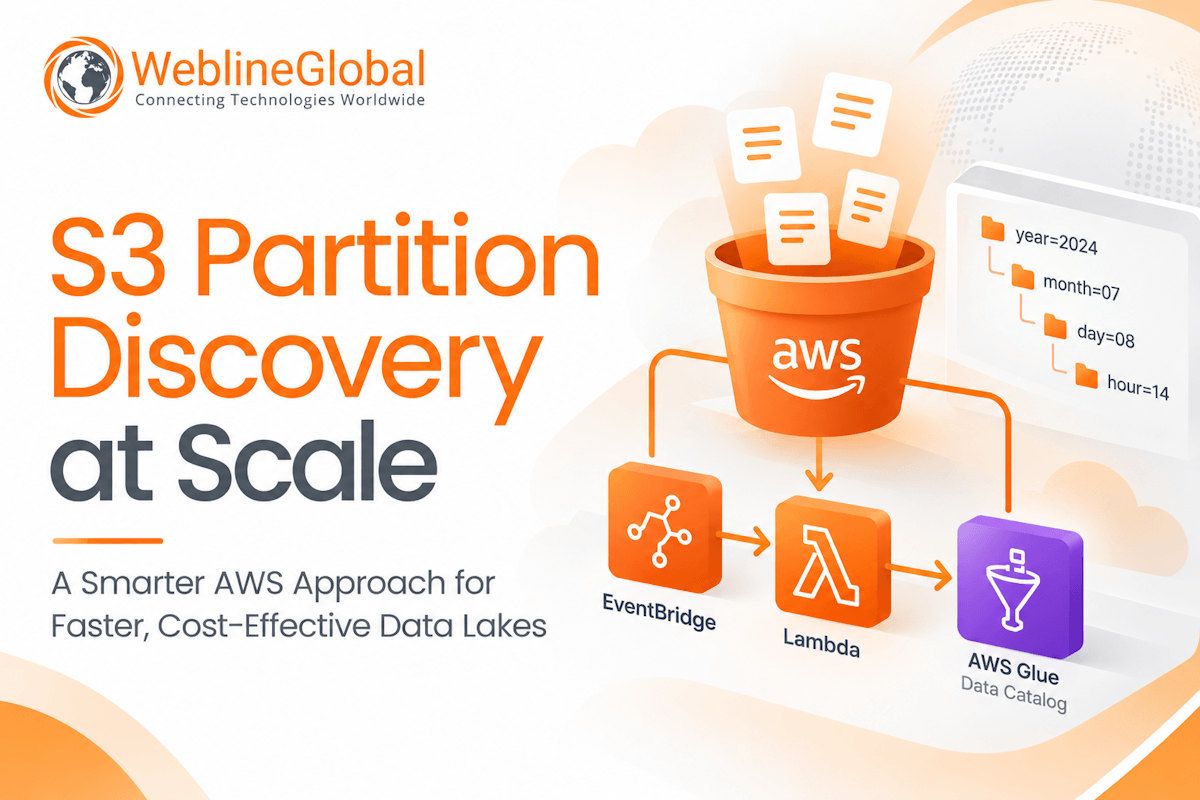
S3 Partition Discovery at Scale: A Smarter AWS Approach

Managing massive Hive-style data lakes on AWS S3 often leads to bottlenecked partition discovery. When ListObjectsV2 becomes too slow and expensive, architects must rethink their approach. Learn how we eliminated recursive S3 prefix scanning and optimized Glue Data Catalog synchronization for a high-volume logistics data platform.